cq.

Birmingham, UK. Research, images & things in progress.

Hello, I’m

Chenyuan Qu.

You can call me Henry.

I’m interested in how we see, how images are made, and what happens when we start playing with them.

This is a collection of my projects, research and things still taking shape.

Explore my work
Editorial portrait
Birmingham, UKA few different sides of me

Selected work

A few things I’ve made.

Some are out in the world. Others are still taking shape. Each began with something I wanted to understand or make better.

Click a detail. Make it yours.
Arrange
Paper
Poster headline selected
Click to edit this element. Drag to move it, or use the arrow keys. Hold Shift to move further.Interactive concept · COMPaD

Allsee × University of Birmingham

A poster is a starting point.

Change a word, move an image, try another colour. I’m exploring how a generated design can leave room for the person who finishes it.

In alpha

The story behind it

I started and lead COMPaD, a joint research project between Allsee and the University of Birmingham.

Instead of delivering one flattened picture, the project keeps text, images, logos and other elements separate. The aim is to give people a first draft they can keep working with.

I designed and trained the text-and-image model using an open-source foundation, and built the tools that turn a brief into a design. We’re in first-stage alpha testing, looking closely at visual quality and whether the results remain useful to edit.

In alpha an editable design, from a short brief.

Research & curiosity

There’s more to an image.

Colour, shape, light, a change of perspective. My research looks at what images can tell us, and how we might work with them.

Take a picture apart.

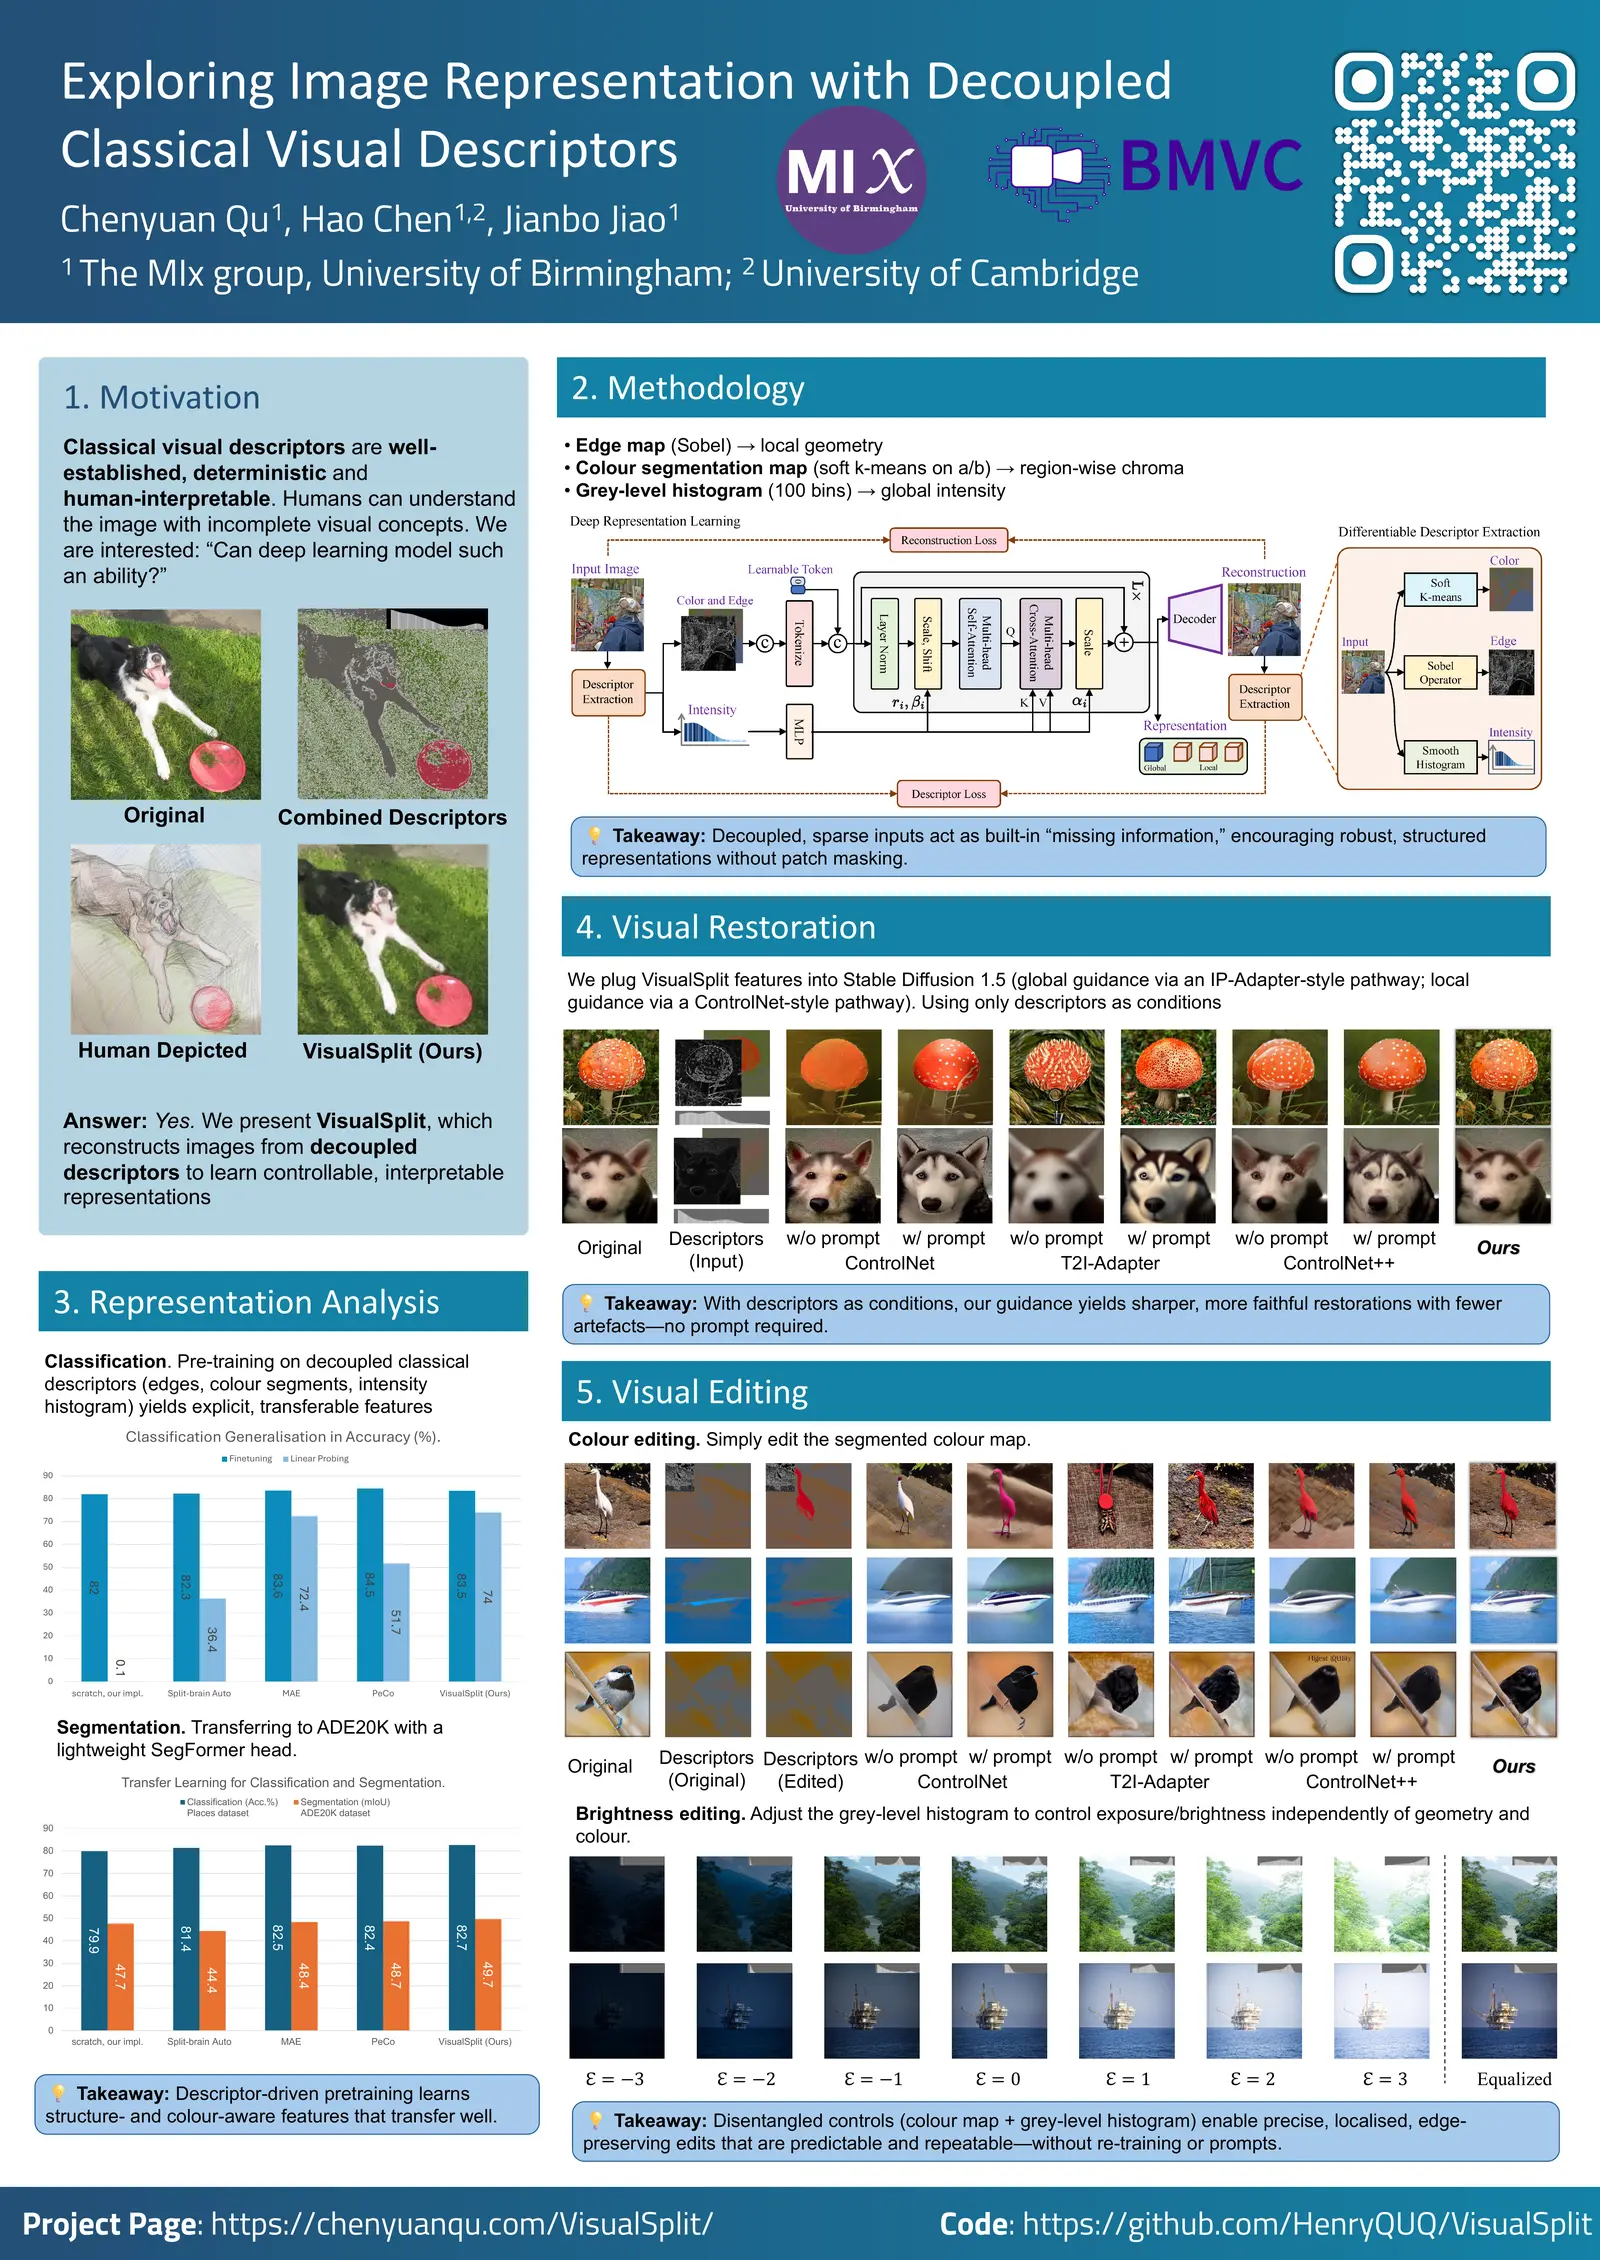
I wanted to give image models controls we can see and understand. VisualSplit starts with three familiar things: shape, colour and light.

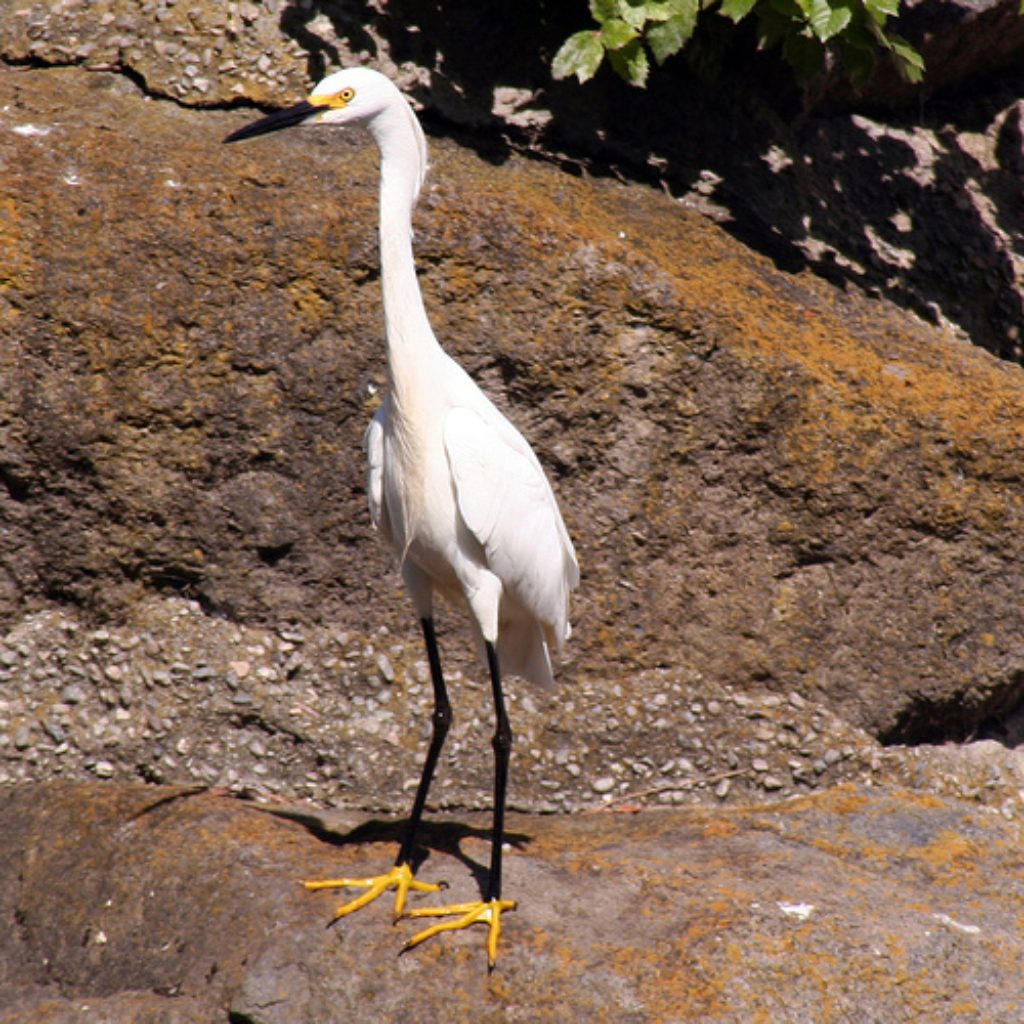
Original photograph of a white egret standing on sunlit rocks
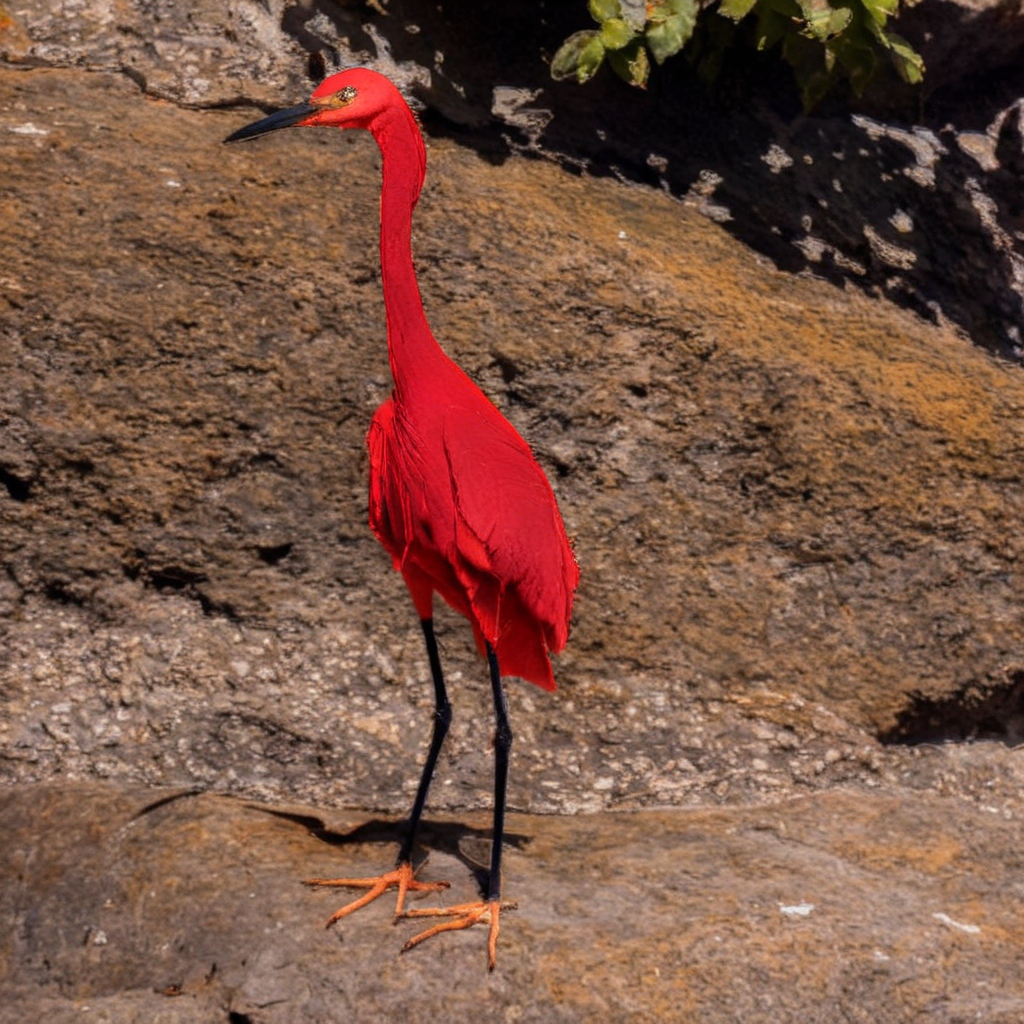
Published VisualSplit colour-editing result: the egret is red against the rocks
Original / VisualSplit resultPublished results

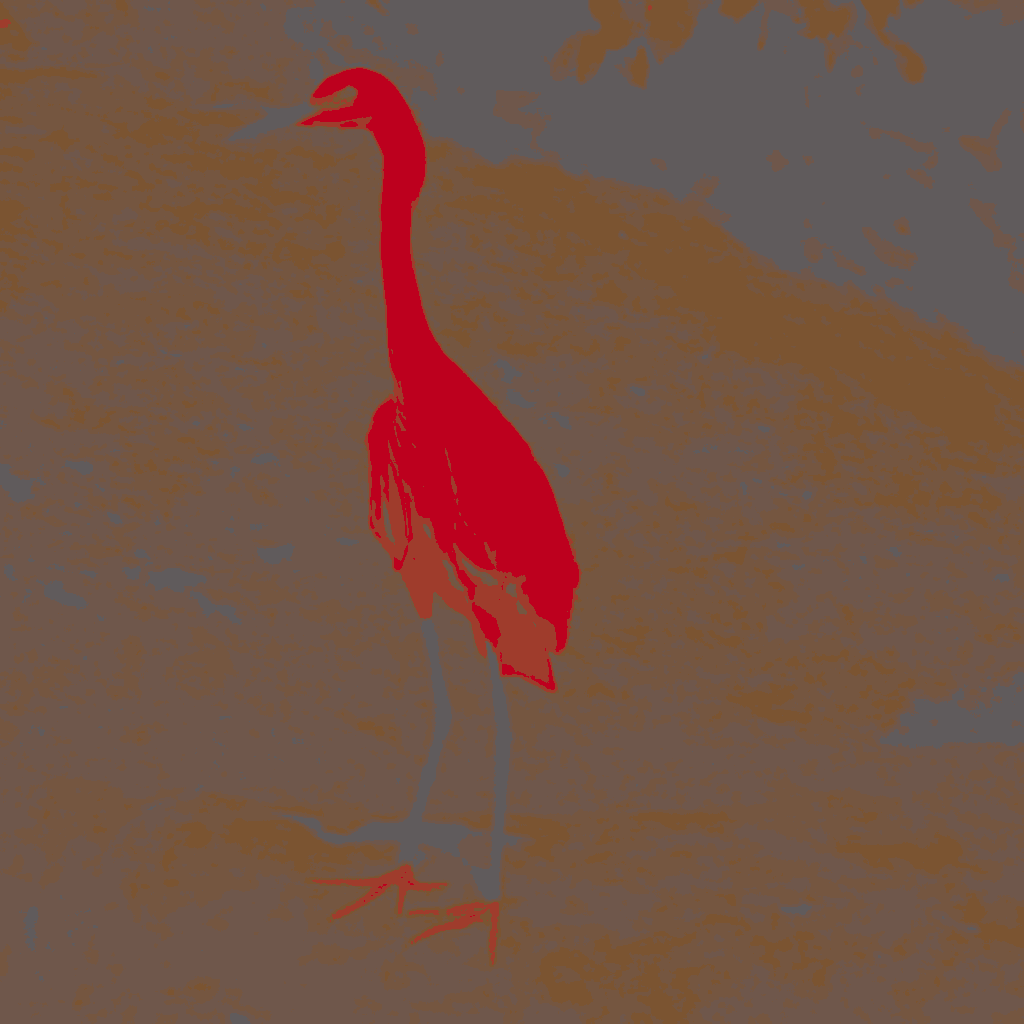
A white bird, in red.

Paint a new colour into the map. The bird’s outline and the scene’s light help guide the new picture. Look closely at what changes, and what stays familiar.

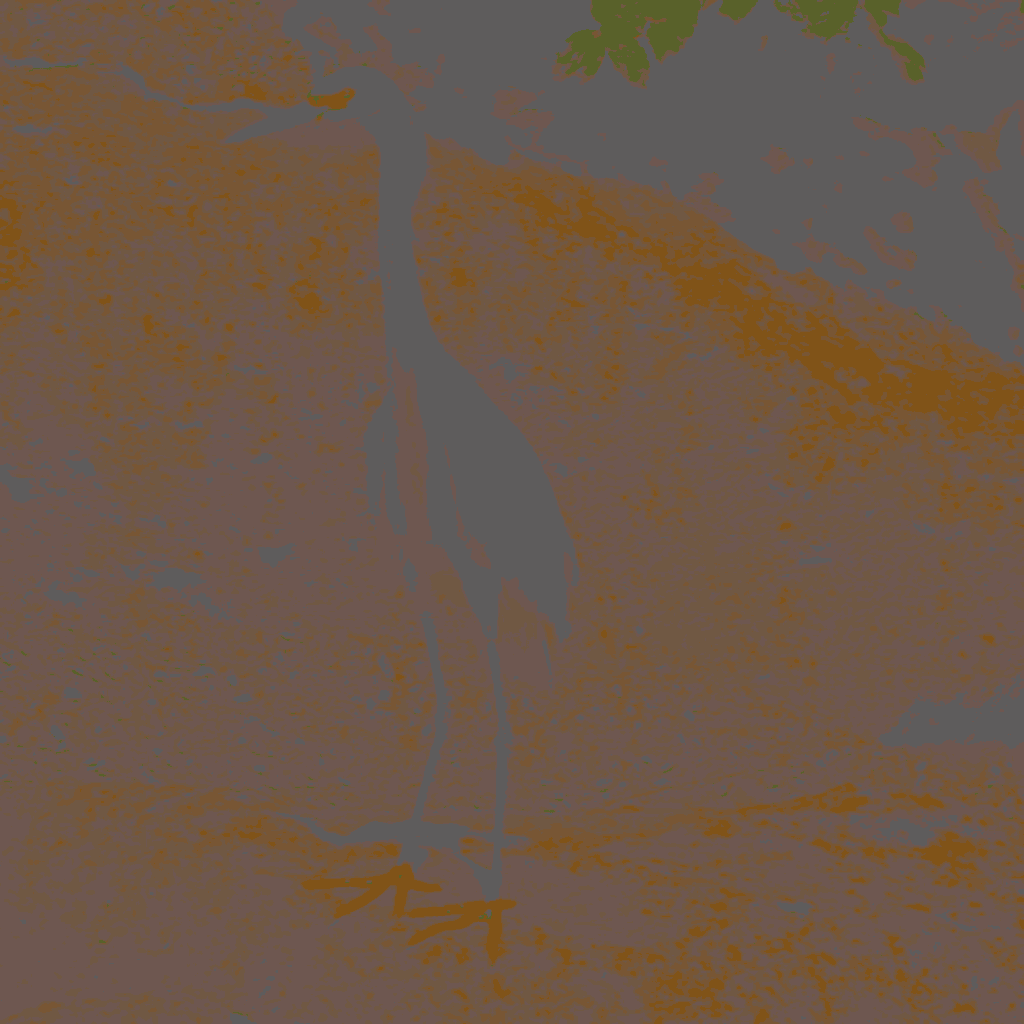
Original colour map of the egret and rocks
Original map
Edited colour map with the egret region painted red
Edited map

The change starts here, in the colour map.

Explore the research
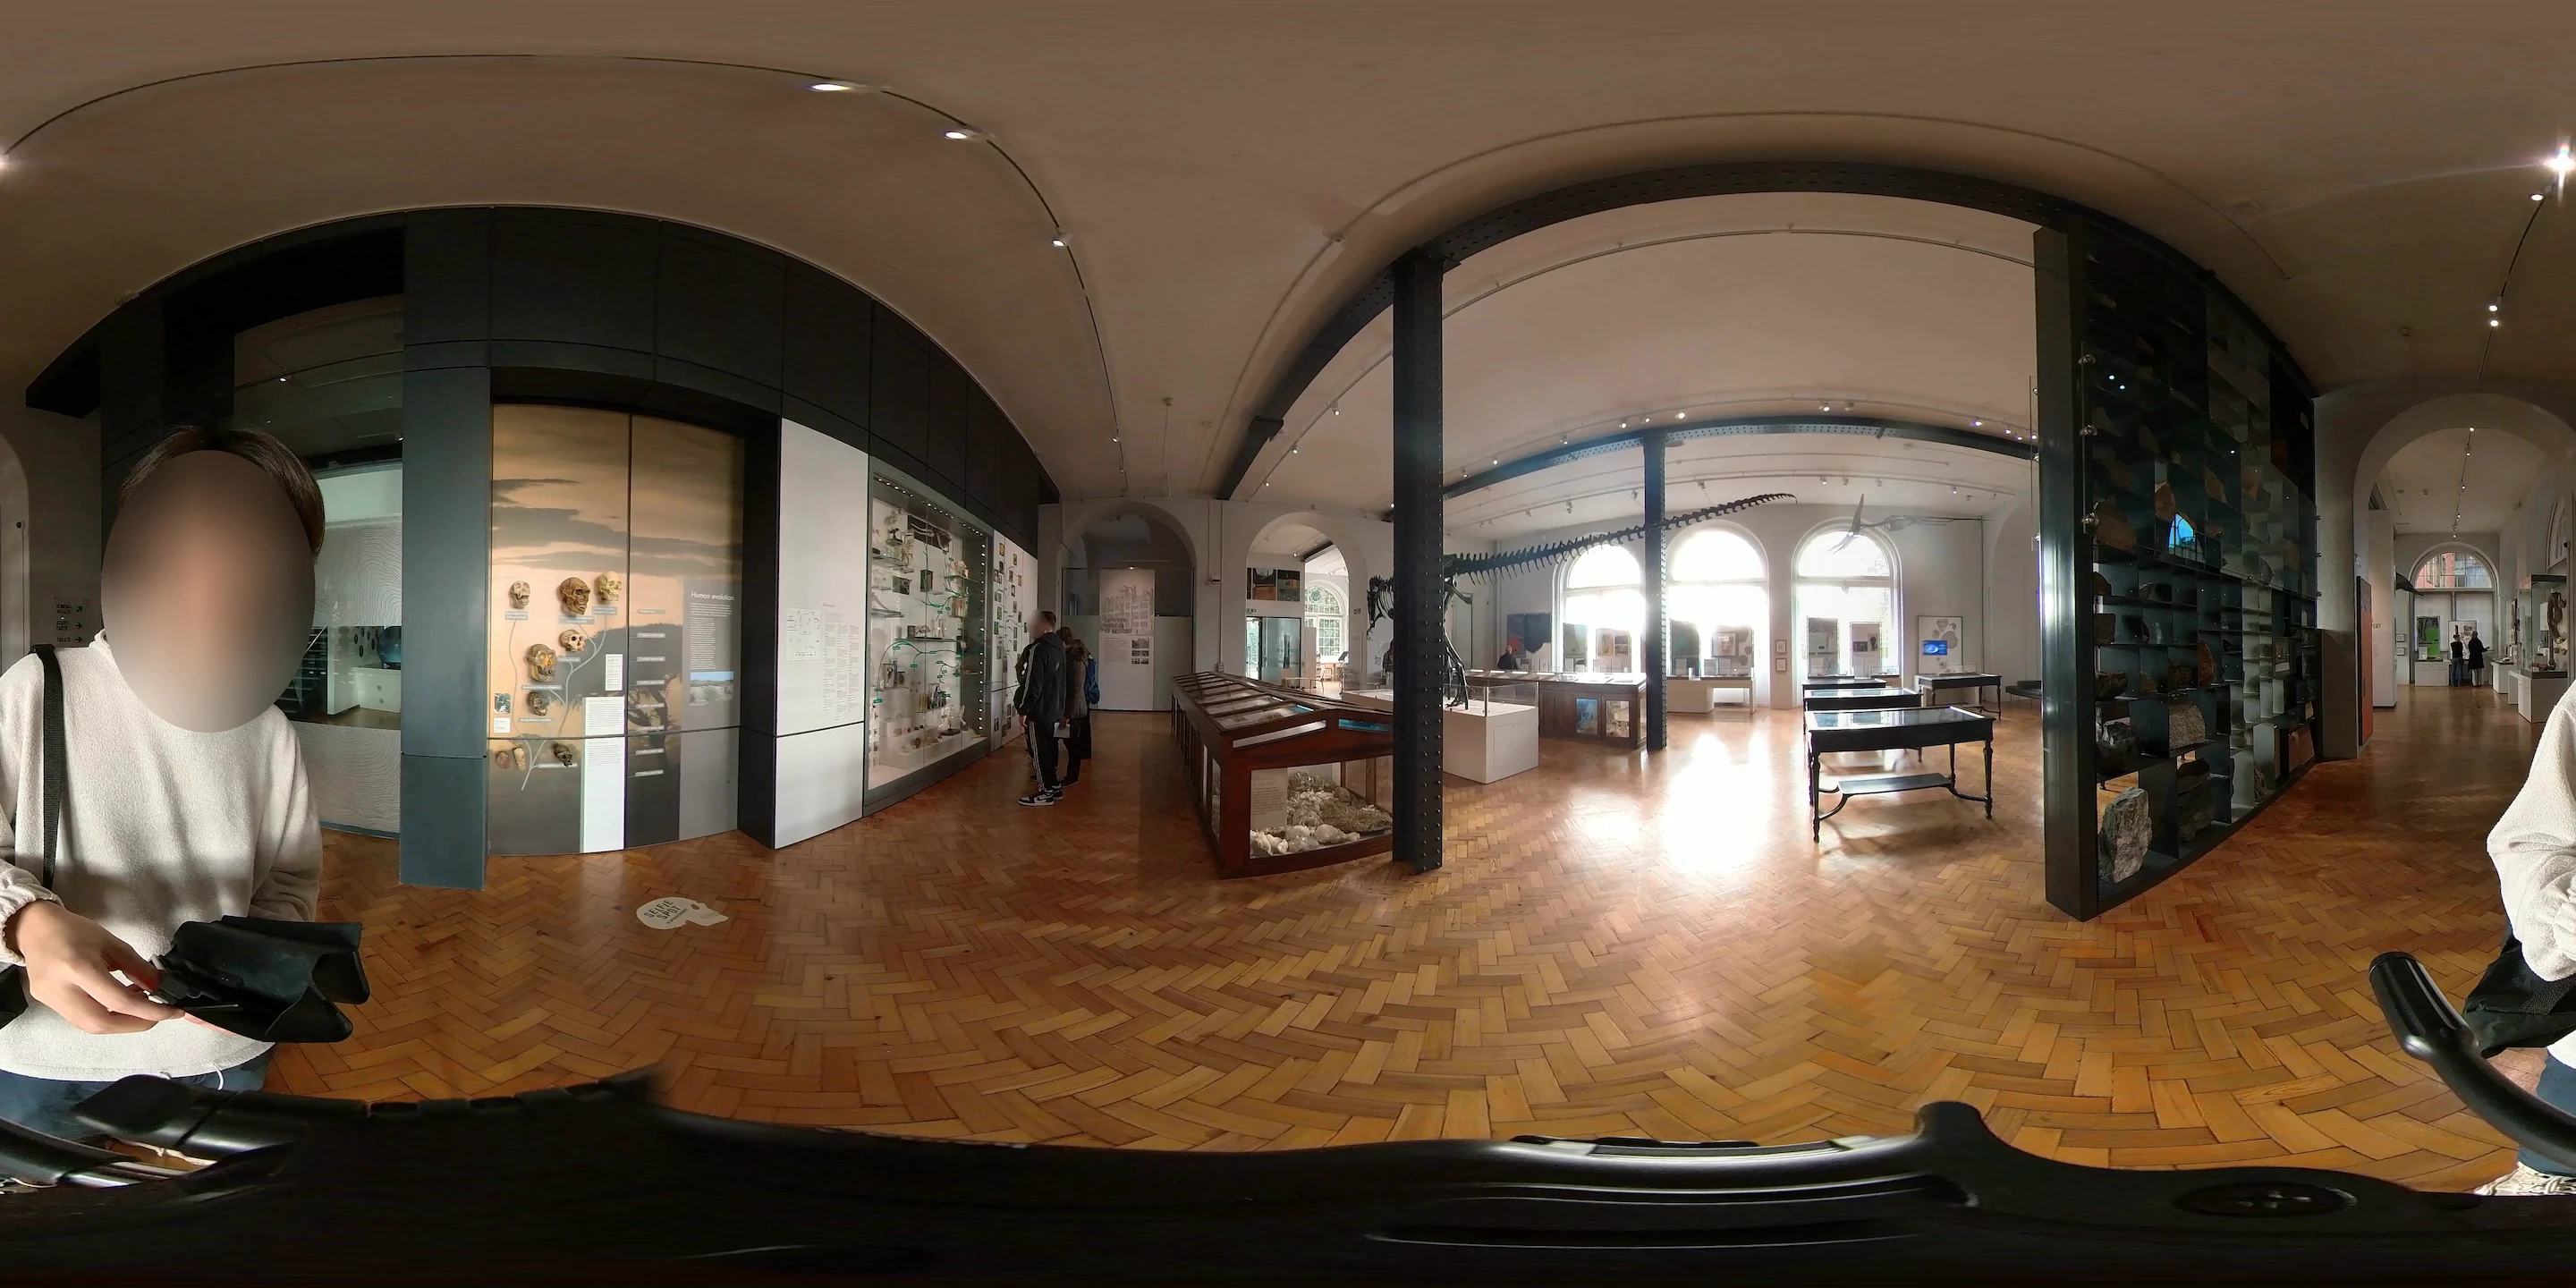
A panoramic museum scene from the official 360+x dataset preview
Drag or use the arrow keys to look around. Home resets the view.

There’s more than one view.

A place is more than the view in front of you. We brought different viewpoints and sound together to study how they add up to a scene. Take a look around.

Explore the project

A little more reading.

2023 2025
2025 BMVCVisualSplitGiving image models controls we can understand.Colour editing · published example

Exploring Image Representation with Decoupled Classical Visual Descriptors

Chenyuan Qu, Hao Chen, Jianbo Jiao

Most neural networks store visual information in features that are difficult to inspect. VisualSplit instead represents an image through edges, colour regions, and a brightness histogram. The model learns to reconstruct the image from those three inputs. Because each input has a clear meaning, it can also be changed directly—for example, to adjust colour or lighting—and reused for image restoration and generation.

Citation & BibTeX

Qu, Chenyuan, Hao Chen, and Jianbo Jiao. "Exploring Image Representation with Decoupled Classical Visual Descriptors." 36th British Machine Vision Conference (BMVC), 2025.

@inproceedings{Qu_2025_BMVC,
  author    = {Chenyuan Qu and Hao Chen and Jianbo Jiao},
  title     = {Exploring Image Representation with Decoupled Classical Visual Descriptors},
  booktitle = {36th British Machine Vision Conference 2025, {BMVC} 2025, Sheffield, UK, November 24-27, 2025},
  publisher = {BMVA},
  year      = {2025},
  url       = {https://bmva-archive.org.uk/bmvc/2025/assets/papers/Paper_873/paper.pdf}
}
Framework overview for VisualSplit showing descriptor decomposition and image reconstruction.Framework overview
Posters & presentation
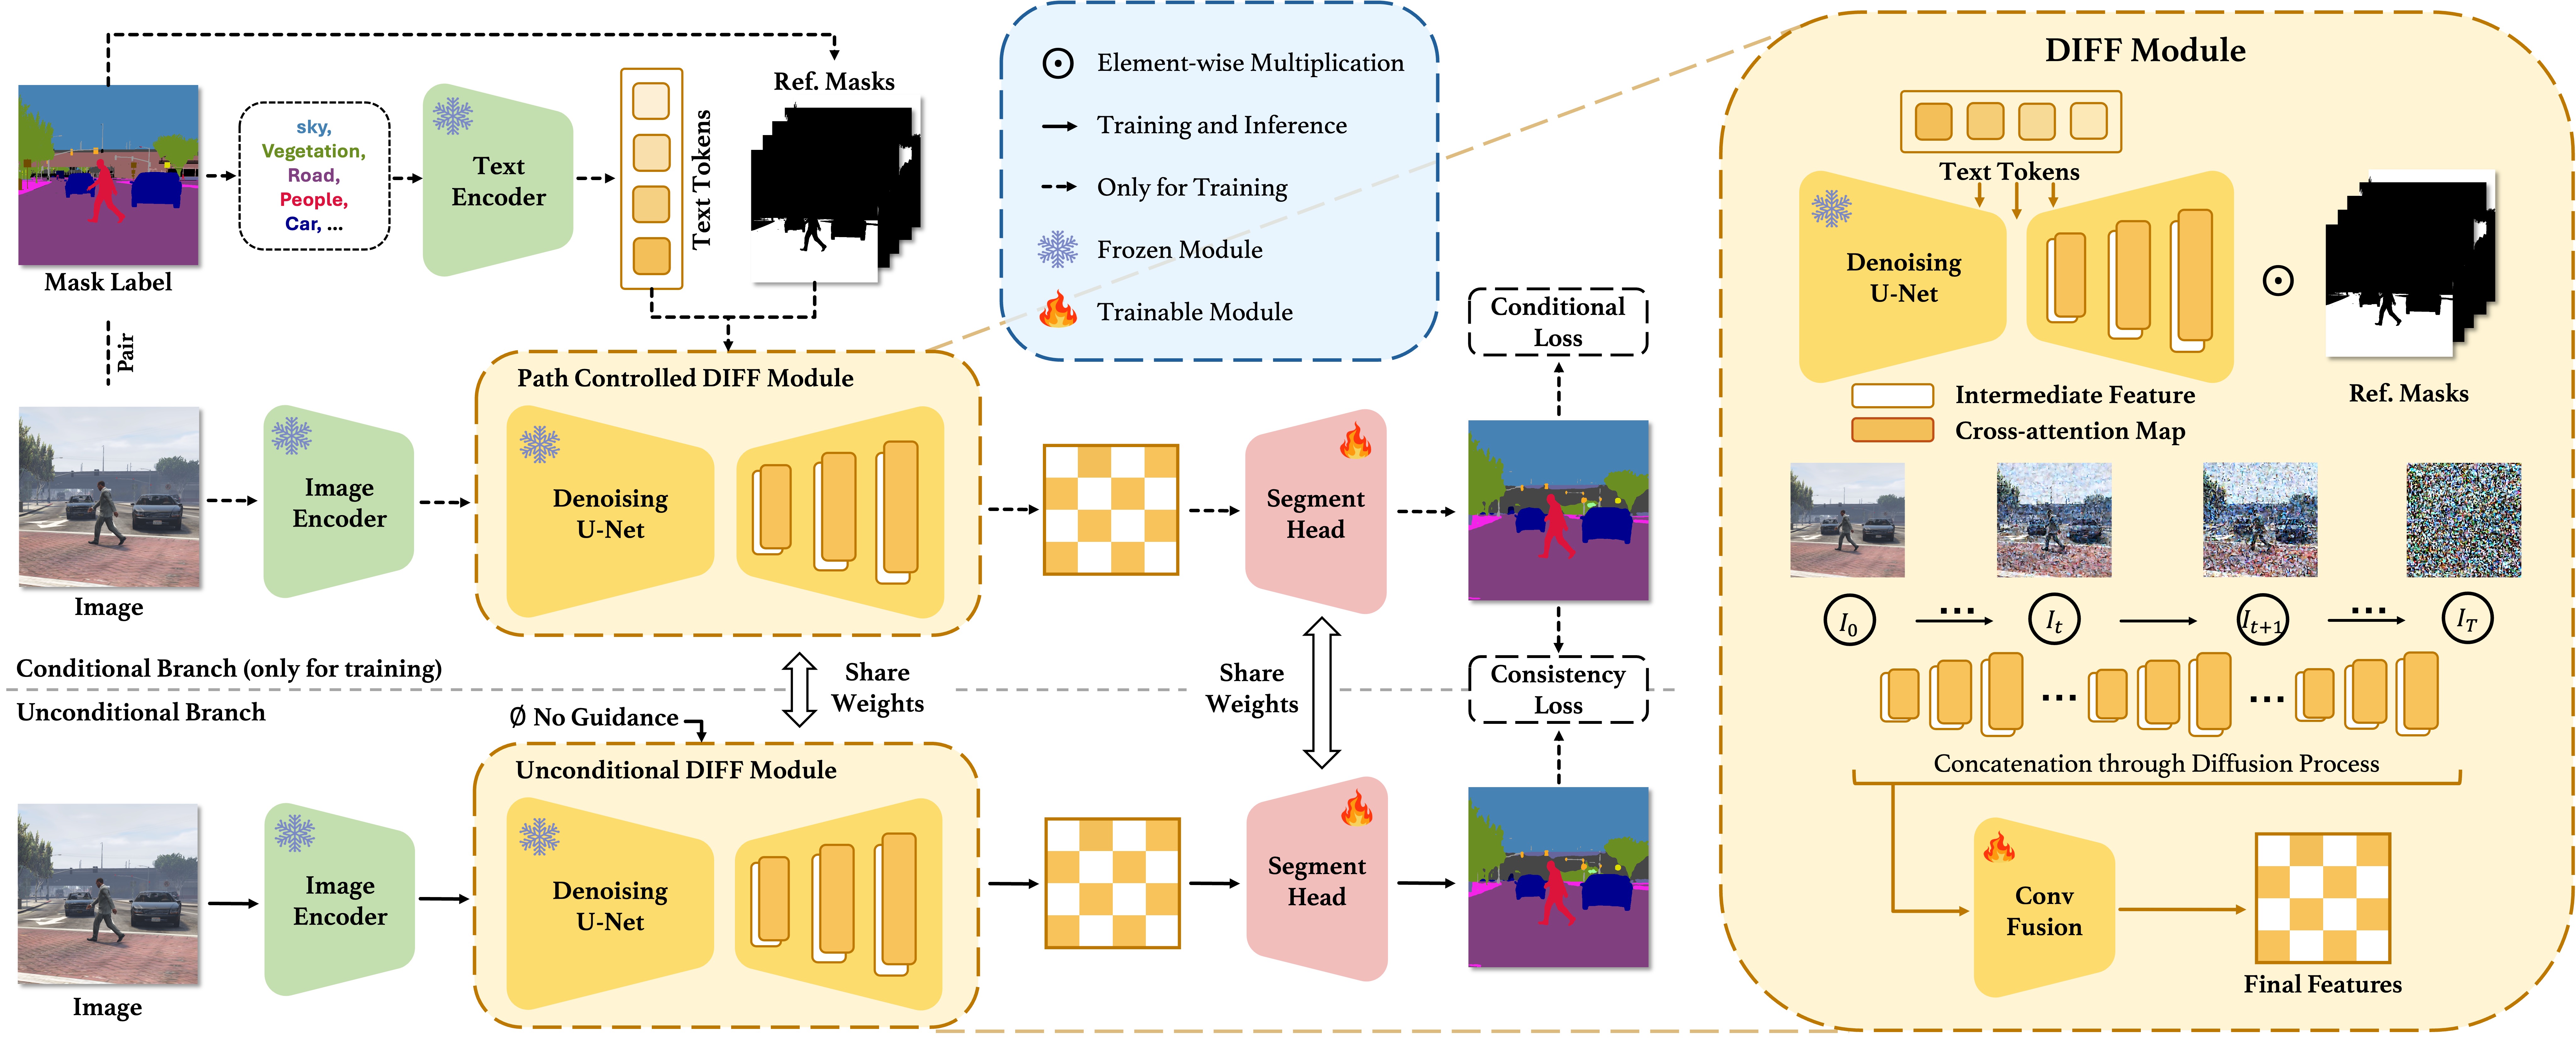
2025 ICASSPDIFFHelping a model recognise a world it hasn’t seen.Image and reference labels · figure detail

Diffusion Features to Bridge Domain Gap for Semantic Segmentation

Yuxiang Ji, Boyong He, Chenyuan Qu, Zhuoyue Tan, Chuan Qin, Liaoni Wu

A model trained to label every pixel in one visual domain can struggle when the style or environment changes. DIFF draws on features from several stages of a diffusion model and combines them into a richer representation. This helps the segmentation model work better on new domains without needing labelled examples from each one.

Citation & BibTeX

Ji, Yuxiang, Boyong He, Chenyuan Qu, Zhuoyue Tan, Chuan Qin, and Liaoni Wu. "Diffusion Features to Bridge Domain Gap for Semantic Segmentation." ICASSP 2025, 1-5.

@inproceedings{DBLP:conf/icassp/JiHQTQW25,
  author       = {Yuxiang Ji and
                  Boyong He and
                  Chenyuan Qu and
                  Zhuoyue Tan and
                  Chuan Qin and
                  Liaoni Wu},
  title        = {Diffusion Features to Bridge Domain Gap for Semantic Segmentation},
  booktitle    = {2025 {IEEE} International Conference on Acoustics, Speech and Signal Processing, {ICASSP} 2025, Hyderabad, India, April 6-11, 2025},
  pages        = {1--5},
  publisher    = {{IEEE}},
  year         = {2025},
  doi          = {10.1109/ICASSP49660.2025.10888537},
  url          = {https://doi.org/10.1109/ICASSP49660.2025.10888537}
}
Official DIFF pipeline overview showing diffusion feature extraction and fusion for cross-domain semantic segmentation.Pipeline overview
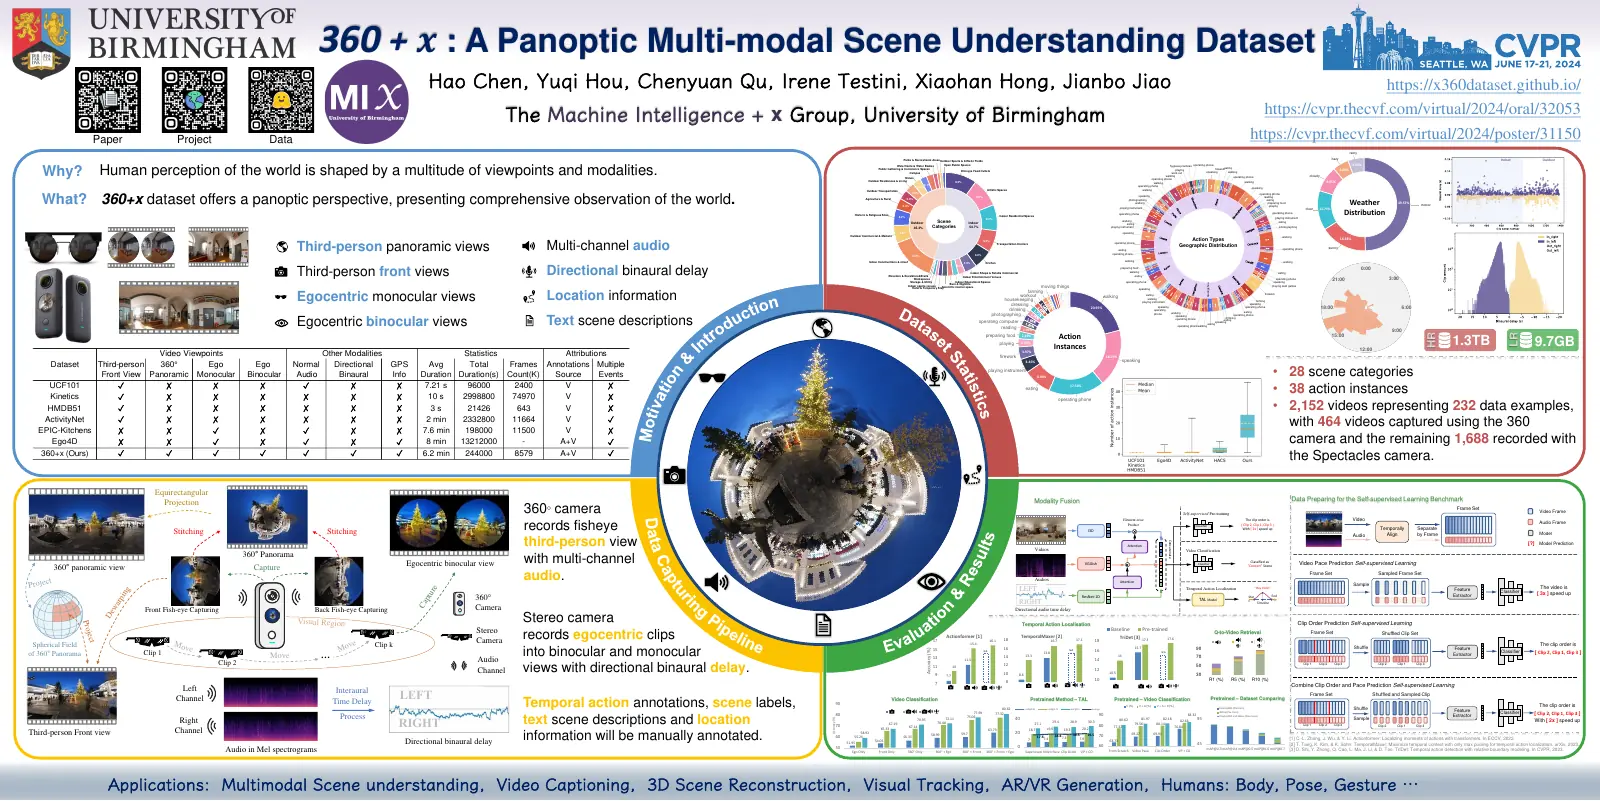
2024 CVPR · Oral360+xUnderstanding a place from more than one perspective.Scene from the dataset

360+x: A Panoptic Multi-modal Scene Understanding Dataset

Hao Chen, Yuqi Hou, Chenyuan Qu, Irene Testini, Xiaohan Hong, Jianbo Jiao

Many datasets show a scene through one camera. 360+x records the same environment through panoramic, front-facing, and first-person views, then aligns them with sound, location, and written context. This lets researchers test whether a model can connect information across viewpoints and data types in real-world settings.

Citation & BibTeX

Chen, Hao, Yuqi Hou, Chenyuan Qu, Irene Testini, Xiaohan Hong, and Jianbo Jiao. "360+x: A Panoptic Multi-modal Scene Understanding Dataset." Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2024.

@inproceedings{chen2024x360,
  title  = {360+x: A Panoptic Multi-modal Scene Understanding Dataset},
  author = {Chen, Hao and Hou, Yuqi and Qu, Chenyuan and Testini, Irene and Hong, Xiaohan and Jiao, Jianbo},
  booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  year   = {2024}
}
Overview figure for 360+x showing the multimodal scene understanding dataset.Dataset overview
Posters & presentation
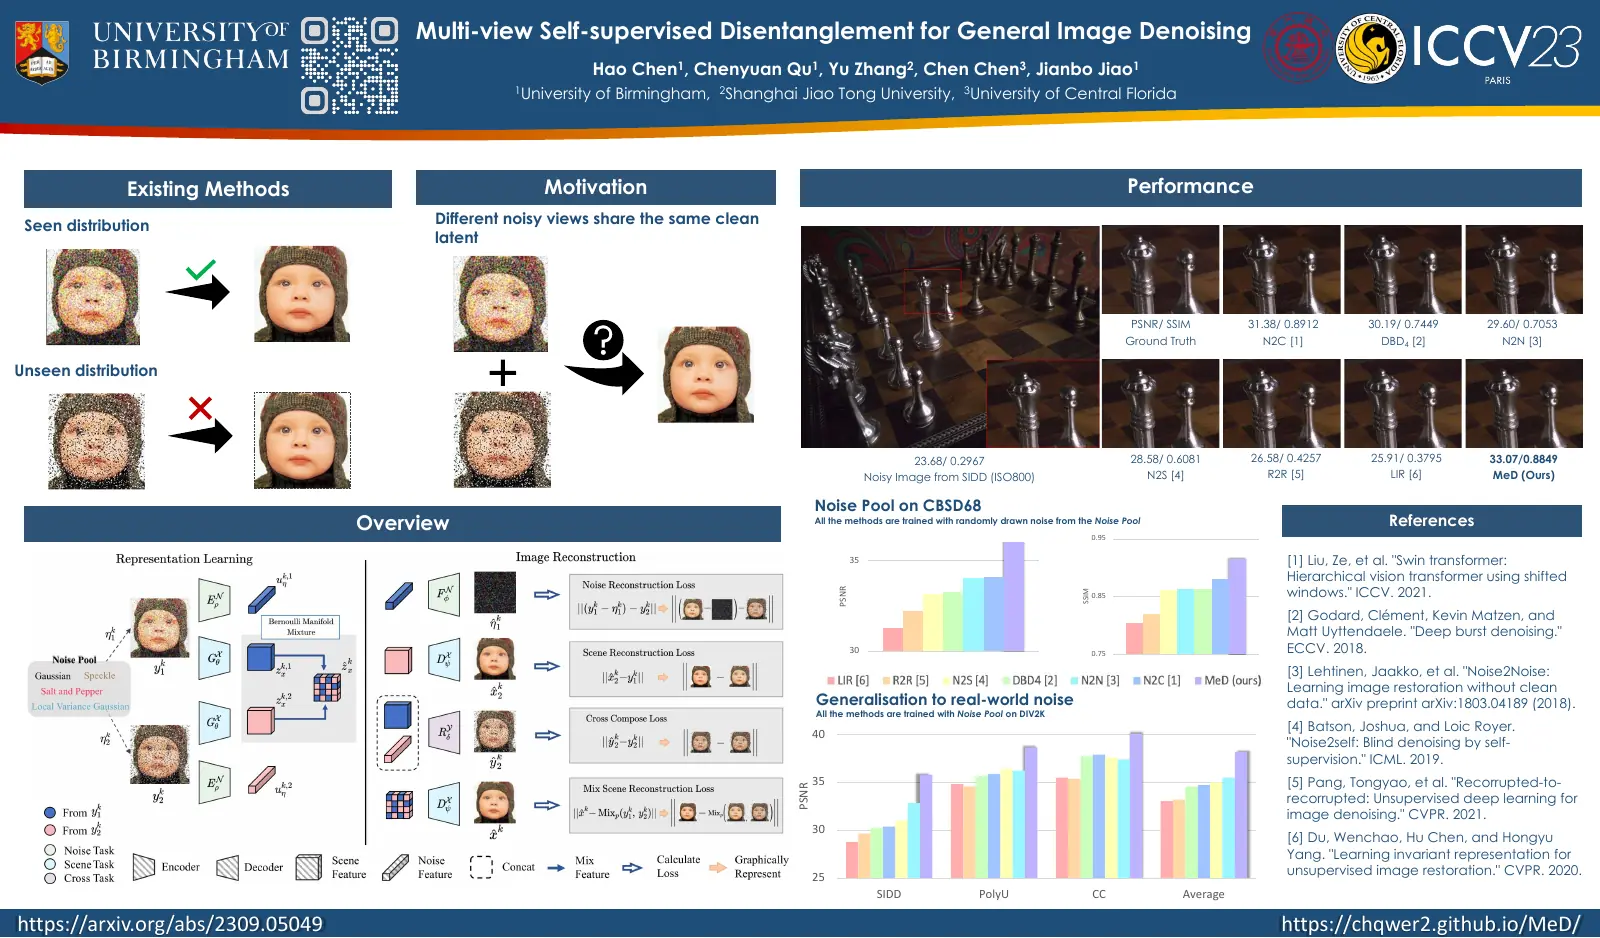
2023 ICCVMeDFinding the picture in the noise.Denoising · published example

Multi-view Self-supervised Disentanglement for General Image Denoising

Hao Chen, Chenyuan Qu, Yu Zhang, Chen Chen, Jianbo Jiao

Training an image-cleaning model usually requires pairs of noisy and clean images, which can be hard to collect. MeD learns from several noisy views of the same scene instead. The visual structure shared by those views is treated as the underlying image, while the differences help the model identify noise. The method was tested on both simulated and real image noise.

Citation & BibTeX

Chen, Hao, Chenyuan Qu, Yu Zhang, Chen Chen, and Jianbo Jiao. "Multi-view Self-supervised Disentanglement for General Image Denoising." Proceedings of the IEEE/CVF International Conference on Computer Vision, 2023.

@InProceedings{MeD_ICCV23,
  author    = {Chen, Hao and Qu, Chenyuan and Zhang, Yu and Chen, Chen and Jiao, Jianbo},
  title     = {Multi-view Self-supervised Disentanglement for General Image Denoising},
  booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV)},
  month     = {October},
  year      = {2023}
}
Method overview for MeD showing the multi-view self-supervised denoising framework.Method overview
Posters & presentation

Shared along the way

BinEgo-360

A research dataset and challenge combining stereo first-person video, 360° views, spatial sound, text, and location information.

Repository
text-to-art-database

A privacy-safe text-to-image dataset on Hugging Face, organised so researchers can load and work with the images more easily.

Chenyuan looking across a busy city crossing at night

Beyond the projects

Still looking. Still learning.

A different point of view.

A little about me

From physics to pictures.

I started with physics at Southampton, then came to Birmingham for a master’s. Somewhere along the way, questions about how the world works became questions about how we see it.

These days, I study computer vision as a part-time PhD researcher at the University of Birmingham and lead technology at Allsee. I like being able to follow an idea through a paper, a prototype, and the conversations it starts.

Find me on LinkedIn
Experience & education

University of Birmingham · MI X Group

Sep 2023 — Expected 2028

PhD Researcher (part-time)

I study how AI can understand and create visual content in ways that are easier to interpret, combine, and control.

Dec 2023 — Present

Research Assistant (part-time)

I research how foundation models represent and combine visual ideas. This work includes COMPaD, the joint Allsee–University of Birmingham project for editable poster generation.

Feb 2023 — Dec 2023

Research Assistant (part-time)

I worked with domain researchers to apply machine learning to hydrology while keeping the results understandable to scientific users.

Allsee · Vieunite

Dec 2024 — Present

Head of Technologies

I lead the company's technology work while continuing to build software myself. My focus includes customer platforms, device software, the ERP, and practical AI tools for everyday work.

Dec 2023 — Dec 2024

Full-stack Engineer

I worked across the customer platform, ERP, cloud services, and device software, helping replace a collection of hardware-specific systems with one shared product.

Sep 2022 — Dec 2023

Algorithm Engineer

I built backend services, recommendation features, and generative-AI tools for Allsee and Vieunite, including features used in the Vieutopia AI art product.

AsiaInfo Software Co. Ltd

Jul 2020 — Sep 2020

Algorithm Engineer Intern

I built and improved machine-learning features for a virtual customer-service presenter designed to run on mobile devices.

Education

2021 — 2022

Master's in Artificial Intelligence and Machine Learning

University of Birmingham

Graduated with Distinction, then continued at Birmingham for research work and a part-time PhD.

2018 — 2021

BSc in Physics

University of Southampton

Physics gave me a strong base in mathematics, modelling, and experimental thinking that I still use in engineering and research.

Recently

2026

COMPaD entered first-stage alpha testing

We’re trying out the first version: can it make a good-looking poster that people can still edit?

A few earlier moments
2023

Started my PhD in the MI X group

I began my part-time PhD in the University of Birmingham's MI X Group, studying how AI can understand images, sound, text, and different viewpoints together.

2023

MeD published at ICCV 2023

This collaborative project learns to remove image noise by comparing several noisy views, without relying on clean target images.

Say hello

Let’s compare notes.

A question about the work, an idea to explore together, or just something you’d like to share. I’d be glad to hear from you.

Chenyuan.Qu@outlook.com